Roman numerals today are written in a strict standard form: a smaller letter goes before a larger one in just six pairs, IV, IX, XL, XC, CD and CM, and no letter repeats more than three times, so the largest number it can write is MMMCMXCIX, or 3,999. Some Roman stonecutters did not keep that rule. The cenotaph of Marcus Caelius, a centurion who fell in AD 9, gives his legion as XIIX, eighteen, and two legionary tombstones write a legion's number as IIII. We ran all three forms through Mark Pilgrim's published pattern for the standard form, and it refused every one. Software splits again at 4,000: Excel's ROMAN function returns an error, the Unicode CLDR rules switch to an archaic numeral character, and one open-source library puts a bar over the V.
Legionary inscriptions ignore the modern subtractive rule
The Caelius stone, CIL XIII 8648, is in Bonn. In the transcription published by Livius.org it calls him a centurion of "leg(ionis) XIIX" who "[ce]cidit bello Variano", fell in the Varian war. The modern form is XVIII; the carver wrote two short of twenty.
The IIII stones are a centurion's tombstone of IIII Flavia Felix from Viminacium, EDCS-30200719, in Livius.org's transcription, and a Mainz tombstone of a soldier of IIII Macedonica, EDCS-10700435. Three stones make no census. IV appears on Roman inscriptions too, and we counted neither form.
Taking two away defeats the simple rule "subtract a letter placed before a larger one", which reads IIX as one plus nine, ten, by our arithmetic. The carver meant eight.
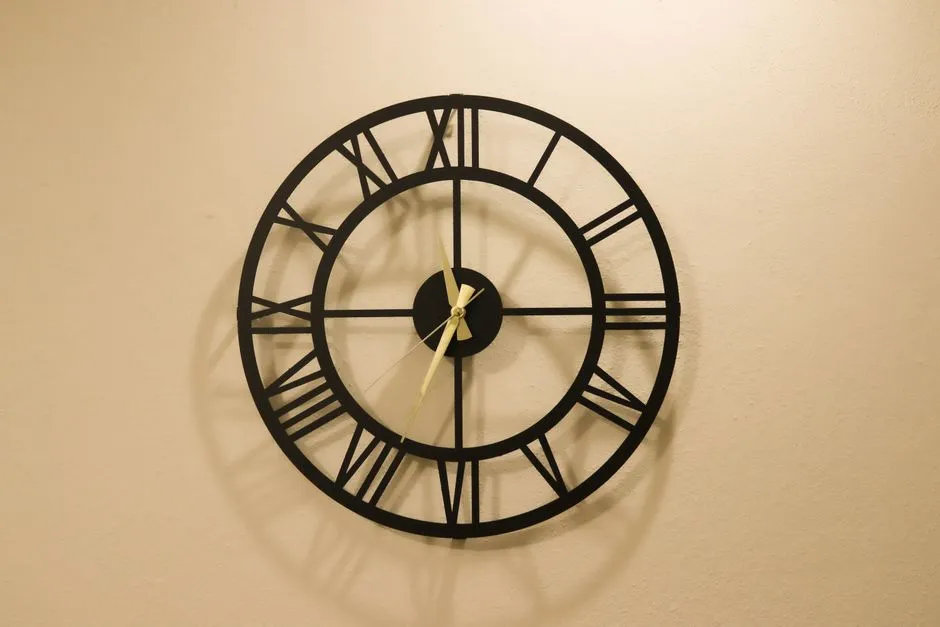
Clock dials follow the additive four in Parliament's and Milham's accounts
A UK Parliament release of 21 March 2019 on the restored North Dial of Westminster's Elizabeth Tower says the 4 o'clock figure "is shown by the Roman numeral IV, rather than the usual IIII on other clocks". The live page refused us; we read an archived copy.
W. I. Milham's Time & Timekeepers, published in October 1923, says IIII "is practically always used instead of IV" on dials, and that when the practice arose and why "are not definitely known". He retells a tale about a clock made for Louis XIV and calls it "probably only a story", since IIII occurs long before that king. Neither counts dials, and we found no primary horological record of the reason.
A strict modern pattern applies a ceiling of 3,999
Pilgrim's pattern, from Dive Into Python 3, is ^M{0,3}(CM|CD|D?C{0,3})(XC|XL|L?X{0,3})(IX|IV|V?I{0,3})$. It allows ten spellings each for hundreds, tens and units, behind up to three Ms, which leaves exactly 3,999 non-empty strings, one per number, on our count. The ceiling is a property of the convention: M{0,3} stops at three thousand and the pattern has no letter for five thousand.
The longest standard form is 3,888, MMMDCCCLXXXVIII, at 15 letters.
Thousands separators got past a converter's digit check
We checked our Roman numeral converter against Pilgrim's pattern on all 137,256 strings of one to six of the seven letters. Each accepted 1,308, with no disagreement, though the converter does not use the regex; it accepts a numeral that converts back to the same letters. Until 19 October 2026 the trouble lay elsewhere. A number typed with a comma converted silently to the wrong numeral: "3,999" came out as III, and all 3,000 comma-grouped inputs from 1,000 to 3,999 went wrong. Unicode Ⅻ was refused, and so was full-width 2026, as a Chinese or Japanese input method types it. For a units eight written IIX, the suggestion was 2 too high on 399 of the 400 numbers ending in 8, and XIIX got "Did you mean XX?". The page's prose cited "[2024] SGCA I", which eLitigation prints as case number 1.
The revised converter turns "3,999" and "3 999" into MMMCMXCIX, refuses "1.000" as a decimal, reads Ⅻ as 12 and writes 2026 as MMXXVI. It still refuses XIIX, since it reads the standard form alone, but now says that read the older way it is 18, written XVIII. On our re-run that reading is right for all 400 IIX-style eights.
Locale rules and code libraries bend the standard form past 3,999
Microsoft's ROMAN page says a number greater than 3999 returns the #VALUE! error. The ARABIC page reads text up to 255 characters and returns up to 255,000. It ignores case, and its own example evaluates "mxmvii" and "MXMVII" to 1997, a form a strict validator rejects; the standard spelling is MCMXCVII.
The CLDR root rules for spelling out numbers write 4,000 as a Latin M followed by ↁ (U+2181, five thousand). They go on through ↂ (U+2182) and ↈ (U+2188) to 399,999, then fall back to ordinary digits.
The big-roman library describes "the overbar extension for numbers 4,000 (MV̅) and above", the bar being U+0305, combining overline. Unicode files ↀ to ↈ under "Archaic Roman numerals", and its names list notes that the reversed C, Ↄ (U+2183), was "used in combination with C and I to form large numbers".
Roman numeral characters exist in Unicode by exception for East Asian encodings
In Unicode 18.0 the range U+2160 to U+2188 holds 41 assigned code points, 40 of them named as Roman numerals; the odd one out is a small reversed C. Thirty-two, Ⅰ (U+2160) to ⅿ (U+217F), decompose to ordinary letters, so Ⅻ (U+216B) becomes XII under compatibility normalisation.
Chapter 22 of the standard says those numerals through 12, plus L, C, D and M, "have been encoded in the Number Forms block … for compatibility with East Asian standards". It names two uses, upright characters in vertical layout and single-character months in compact dates, and warns that in identifiers they can lead to spoofing.
We parsed seven East Asian mapping tables that Unicode publishes. Big5 and Microsoft's Big5, used in Taiwan and Hong Kong, carry ten each, Ⅰ to Ⅹ. Microsoft's GBK table for mainland China carries 22. KS X 1001, Microsoft's Korean table and the Windows Japanese table carry 20 each, while JIS X 0208-1990 carries none. Across them, 22 of the 32 appear, and Unicode marks the same 22 as East Asian Width "Ambiguous". Three tables, BIG5.TXT among them, sit in Unicode's obsolete folder, and that file calls its contents possible mappings. Big5 itself is covered in why a character breaks in Big5.
Zero falls under a separate rule in the CLDR locale data
The standard form has no zero, negatives or fractions, and the CLDR rules handle each separately. Zero is written N. A negative number takes a minus sign. Anything with a fractional part leaves Roman letters altogether and prints as a decimal to two places.
For fractions, at least one Roman carver had a solution. The Caelius stone gives the centurion's age as "LIII s(emis)", fifty-three and a half, using an S for semis. Unicode's own advice for ordinary text argues against using its special characters: "For most purposes, it is preferable to compose the Roman numerals from sequences of the appropriate Latin letters."
View author profile → · Editorial policy